
A pump begins to vibrate more than usual. A bridge-monitoring system records a handful of strain readings. A battery model must predict temperature inside a cell where no sensor can be placed. In each case, engineers need an answer before they have perfect data, unlimited computing power, or time for a full-scale experiment.
Traditional engineering analysis offers powerful tools: conservation laws, differential equations, numerical simulation, and carefully calibrated measurements. Modern machine learning offers another: models that find patterns in data. Yet each approach has a weakness when used alone.
A simulator can be slow or depend on uncertain inputs. A purely data-driven neural network can fit observations while predicting behavior that violates known physics. Physics-informed neural networks, commonly called PINNs, aim to connect these two worlds.
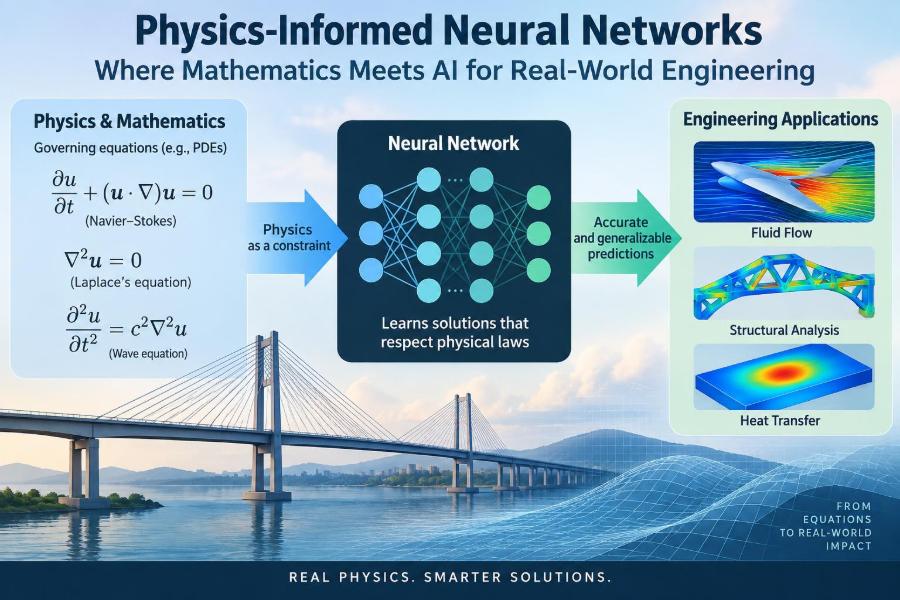
The idea is not to replace engineering mathematics with artificial intelligence. It is to use mathematics as a constraint, guide, and diagnostic tool while AI learns from data. That combination is promising—but it also requires careful modeling, validation, and realistic expectations.
🧭 The Engineering Problem PINNs Address
Many engineering systems are governed by partial differential equations, or PDEs. These equations describe how a quantity changes across space and time: heat through a plate, pressure in a pipe, displacement in a beam, or concentration in a reactor.
To solve a PDE conventionally, engineers define geometry, material properties, boundary conditions, initial conditions, and forcing terms. They then use methods such as finite elements, finite volumes, or finite differences.
PINNs become attractive when some of those ingredients are incomplete, when measurements are sparse, or when repeated simulations would be too expensive. They can estimate an unknown field while being penalized for breaking the governing equations.
📚 What a Physics-Informed Neural Network Is
A PINN is a neural network trained to approximate a physical quantity, such as temperature T(x,t), velocity, pressure, or displacement. Its inputs usually include coordinates such as position and time; its outputs are predicted field values.
What makes it physics-informed is the loss function. Instead of minimizing only the difference between predictions and observations, training also minimizes the residual of the governing equation.
For a heat-transfer problem, the network is not merely asked to match sensor temperatures. It is also encouraged to produce a temperature field consistent with heat diffusion throughout the domain.
🧮 The Mathematical Core: Differential Equation Residuals
Consider the one-dimensional heat equation:
∂T/∂t = α ∂²T/∂x²Here, T is temperature, x is position, t is time, and α is thermal diffusivity. If a neural network predicts T̂(x,t), we can substitute that prediction into the equation.
The leftover mismatch is called the physics residual:
r(x,t) = ∂T̂/∂t - α ∂²T̂/∂x²A perfect solution has a residual of zero everywhere. In practice, a PINN samples many points in the domain and reduces the residual during training.
🔗 Why Derivatives Are Possible in a Neural Network
A standard neural network is a chain of differentiable operations. Because of that structure, software can calculate derivatives of its output with respect to its inputs using automatic differentiation.
Automatic differentiation is not the same as estimating a derivative from nearby values with a finite-difference formula. It applies the chain rule through the computational graph, usually giving derivatives that are consistent with the represented network function.
This capability allows a PINN to calculate terms such as spatial gradients, time derivatives, and second derivatives while it is being trained. Without it, enforcing many differential equations would be far less convenient.
⚖️ The Loss Function Combines Several Obligations
Most PINNs minimize a weighted combination of losses. A simple conceptual form is:
Loss = w_data L_data + w_PDE L_PDE + w_BC L_BC + w_IC L_ICThe terms represent different engineering obligations:
- Data loss: agreement with measured values.
- PDE loss: agreement with the governing differential equation at sampled interior points.
- Boundary-condition loss: agreement with conditions at edges, walls, supports, or interfaces.
- Initial-condition loss: agreement with the known state at the starting time.
The weights matter. If the data term dominates, the model may fit noisy readings and neglect physics. If the PDE term dominates, it may satisfy an idealized equation while missing real behavior in the measurements.
🚪 Boundary Conditions Are Not Minor Details
Boundary conditions often determine whether a mathematical model represents the actual engineering system. A wall may be held at a fixed temperature, insulated, exposed to convection, or connected to another material. These are physically different statements.
For structural mechanics, a support might fix displacement but allow rotation, or it may resist both. In fluid flow, an inlet velocity profile and an outlet pressure condition shape the solution.
A PINN cannot rescue a vague or incorrect boundary condition. In fact, sparse data can make the resulting error harder to detect because the network may produce a smooth, believable field that solves the wrong problem.
🧱 Hard Constraints and Soft Constraints
Most PINNs enforce conditions softly by adding penalty terms to the loss. This is flexible, but the network may still violate an essential boundary condition slightly after training.
A hard constraint builds a known condition directly into the network output. For example, if displacement must be zero at x = 0, an approximation might be written as u(x) = xN(x), where N(x) is the neural-network output.
Hard constraints can improve reliability for simple geometries. They are not always easy to construct, especially for complicated boundaries, coupled systems, or conditions involving fluxes rather than values.
🌡️ A Simple Heat-Conduction Example
Imagine a metal bar heated at one end and cooled at the other. A conventional analysis could solve the heat equation after specifying the bar dimensions, conductivity, heat capacity, and boundary temperatures.
Now suppose temperature is measured at only a few interior locations, while the heat-transfer coefficient at the outer surface is uncertain. A PINN can represent the temperature field and treat that coefficient as an unknown parameter to infer during training.
This is a hypothetical illustration, not a guarantee that every thermal problem is identifiable. If the sensors are poorly placed or the experiment does not excite the relevant behavior, several parameter values may explain the data almost equally well.
🌊 Fluid Mechanics Is a Natural but Difficult Application
Fluid systems generate large amounts of spatially and temporally varying behavior. The governing equations, including the Navier–Stokes equations, connect velocity, pressure, density, viscosity, and external forces.
PINNs can be used to reconstruct flow fields from limited measurements, estimate pressure from velocity data, or learn unknown constitutive parameters. Their appeal is especially clear where direct pressure measurement or full-field flow visualization is impractical.
However, turbulent, high-Reynolds-number, and strongly multiscale flows remain demanding. Small scales, sharp gradients, and uncertain turbulence modeling can make training difficult. A PINN should not be assumed to outperform established computational fluid dynamics methods on every flow problem.
🏗️ Structural Mechanics and Material Behavior
In solid mechanics, the governing relationships combine equilibrium, strain-displacement relations, and material constitutive laws. A PINN can approximate displacement fields while enforcing these equations.
Potential uses include identifying elastic parameters from displacement measurements, estimating stress in regions where strain gauges cannot be installed, and incorporating data from structural health monitoring.
The material model deserves scrutiny. An elastic PDE may be unsuitable for a component with plastic deformation, cracking, creep, contact, or hysteresis. The neural network may converge neatly while the assumed constitutive law remains physically inappropriate.
🔋 Electrochemical and Energy Systems
Batteries, fuel cells, and thermal energy systems involve coupled transport processes. Temperature, charge, concentration, and reaction rates can influence one another, sometimes across several physical scales.
Physics-informed models may help estimate hidden internal states from accessible signals such as voltage, current, and surface temperature. This is useful because internal measurements can be difficult, disruptive, or unavailable during normal operation.
Yet a model used for operational decisions must be validated across relevant loads, temperatures, aging states, and fault conditions. A training dataset collected under calm laboratory conditions may not represent field operation.
🛰️ Sparse Sensors Become More Informative
A sensor reports a local quantity, not the entire state of a system. Physics provides relationships that carry information from one location to another. PINNs use those relationships to infer a continuous field from discrete observations.
That does not create information from nothing. Instead, it combines measurements with assumptions embedded in the governing equations, geometry, parameterization, and boundary conditions.
This distinction matters when evaluating results. A dense-looking color map from a PINN is partly observation and partly model-based inference. Engineers should communicate that uncertainty rather than treating every pixel as directly measured.
🔍 The Inverse Problem: Learning Unknown Parameters
A forward problem starts with parameters and predicts behavior. An inverse problem starts with observed behavior and estimates parameters that may have produced it.
PINNs can handle inverse problems by making quantities such as diffusivity, stiffness, damping, permeability, or source strength trainable. The model then adjusts both the field and the unknown parameters to reduce the combined loss.
Inverse problems can be ill-posed: small measurement errors may cause large changes in inferred parameters, or different parameter sets may fit the same data. Physical bounds, independent tests, and uncertainty analysis are often needed.
🧪 Forward, Inverse, and Hybrid Tasks Compared
| Task | Known inputs | Main output | Typical challenge |
|---|---|---|---|
| Forward simulation | Parameters, conditions, geometry | Physical field or response | Computational cost |
| Inverse identification | Measurements and partial physics | Unknown parameters or sources | Non-unique answers |
| Data assimilation | Model plus streaming or sampled data | Updated state estimate | Noise and changing conditions |
| Surrogate modeling | Many prior simulations or experiments | Fast approximation | Generalizing beyond training range |
A single PINN framework may be adapted to each task, but the quality criteria differ. A fast surrogate is judged by prediction error and speed, while an inverse model must also be judged by parameter identifiability and uncertainty.
🧠 PINNs Are Not Just “AI That Knows Physics”
The phrase can be misleading. A PINN does not possess physical understanding in the human sense, and it does not automatically choose the correct equation for a new system.
Its physics comes from what engineers explicitly encode: equations, constraints, parameter ranges, coordinate definitions, and loss terms. The network is an approximation mechanism optimized under those rules.
This is useful because it clarifies responsibility. Better results usually come from better problem formulation, better measurements, and better validation—not merely from adding more layers to the network.
🖥️ PINNs Versus Finite Element and Finite Volume Methods
Finite element methods and finite volume methods discretize the physical domain into elements or control volumes. They have mature theory, established workflows, and strong performance for many engineering problems.
PINNs use a different representation: a continuous neural approximation evaluated at selected points. They can be convenient for combining scattered data with physics and for differentiating the learned field.
These approaches are often complementary rather than rivals. A conventional solver can generate training data, verify a PINN on benchmark cases, or supply a high-fidelity reference for critical design decisions.
⏱️ When a PINN Can Save Time—and When It Cannot
A PINN may be worthwhile when one model must fuse diverse measurements, estimate hidden quantities, or answer many related queries after training. It may also help where meshes are difficult to generate or geometry changes modestly across a family of problems.
But training can be expensive and temperamental. For one well-defined simulation with reliable parameters, a conventional numerical solver may be faster, easier to audit, and more accurate.
The relevant question is not “Which method is more advanced?” It is “Which workflow gives a trustworthy answer for this decision, with the available data and computational budget?”
📉 Training Difficulty: Stiffness and Competing Scales
Engineering equations often contain variables with very different magnitudes or time scales. A thermal response may evolve slowly while an electrical transient changes rapidly. Such systems are sometimes called stiff.
During PINN training, gradients from one part of the loss can overwhelm others. The network may learn the smooth, easy part of the solution while missing sharp layers, fast transients, or localized sources.
Normalization, nondimensionalization, adaptive loss weighting, and targeted point sampling can help. These methods improve conditioning, but they do not remove the need to inspect errors in the features that matter most.
📍 Collocation Points Determine Where Physics Is Enforced
PINNs enforce PDE residuals at selected locations called collocation points. They are not necessarily sensor locations; they are mathematical checkpoints in the domain.
Uniform random points can work for simple problems, but they may undersample boundary layers, wave fronts, cracks, shocks, or interfaces. In those regions, physics residuals can be large even if the global average looks acceptable.
Adaptive sampling adds points where residuals or estimated errors are high. This directs training effort toward difficult regions, much like mesh refinement in conventional numerical analysis.
📏 Nondimensionalization Is a Practical Superpower
Nondimensionalization rescales variables using meaningful reference quantities. For instance, temperature may be scaled by a characteristic temperature difference, length by component size, and time by a diffusion time scale.
This makes variables closer to comparable numerical ranges and reveals dimensionless groups such as the Reynolds number, Peclet number, or Biot number. Those groups also help engineers understand which effects dominate.
For PINNs, sensible scaling often improves optimization substantially. It is not a cosmetic preprocessing step; it is an application of engineering mathematics that changes the numerical character of the training problem.
🧹 Noisy Data Require Judgment, Not Blind Fitting
Measurements contain sensor error, timing mismatch, drift, missing values, and occasional faults. A flexible neural network can fit these imperfections if data loss is emphasized too strongly.
Physics constraints can regularize the solution, meaning they discourage implausible fluctuations. But a physics model can also be imperfect, particularly in real equipment with unmodeled heat losses, friction, damage, or changing properties.
Useful practice includes checking sensor calibration, preserving raw data, documenting filtering choices, and testing sensitivity to plausible noise levels. A smooth result is not automatically a reliable result.
🧩 Model Discrepancy Cannot Be Wished Away
Every governing equation is a model of reality, not reality itself. A beam equation may neglect joint flexibility; a flow model may neglect roughness changes; a thermal model may use properties that vary more than assumed.
If observed data consistently conflict with the encoded PDE, that conflict is valuable information. It may indicate a sensor issue, an incorrect condition, an omitted mechanism, or operation outside the assumed regime.
Forcing the PINN to reconcile incompatible assumptions can produce biased parameters and misleading fields. Engineers should investigate persistent residual patterns rather than treating them solely as optimization failures.
✅ Validation Needs More Than a Low Training Loss
A low loss shows that the chosen objective was optimized. It does not prove that the resulting model predicts accurately in the intended application.
Validation should use data or cases not used during fitting whenever possible. For a simulated benchmark, compare against a trusted numerical solution. For a physical system, compare against independent sensors, test conditions, or experiments.
- Check errors at boundaries, interfaces, peaks, and transients—not only averages.
- Assess whether inferred parameters remain plausible under small data changes.
- Test conditions near the expected operating envelope.
- Report failure cases as well as successful examples.
For safety-critical decisions, a PINN should sit within a documented verification and validation process, not outside it.
📊 Uncertainty Should Accompany Predictions
A single predicted field can suggest false certainty. Uncertainty may arise from noisy data, uncertain geometry, unknown parameters, imperfect equations, or limited coverage of operating conditions.
Different approaches can represent uncertainty, including ensembles of trained models, Bayesian formulations, repeated fits to resampled data, and propagation of uncertain inputs. Each has computational and interpretive trade-offs.
Even a simpler sensitivity analysis is valuable: vary key boundary conditions or material properties within credible ranges and observe whether the engineering conclusion changes. If it does, the decision may require more data or a more robust design margin.
🛠️ A Sensible Engineering Workflow
PINN projects benefit from the same discipline as other computational models. Begin with the engineering decision, not the neural-network architecture.
- Define the quantity to estimate and the decision it will support.
- Write the governing equations, assumptions, units, conditions, and parameter bounds.
- Inspect data quality, sensor locations, synchronization, and coverage.
- Create a simple baseline using analytical reasoning or a conventional solver.
- Train the PINN with scaled variables and carefully chosen loss terms.
- Validate against held-out cases and investigate discrepancies.
- Document the valid operating range and known limitations.
This sequence reduces the risk of producing an impressive visualization without a defensible engineering interpretation.
🚧 Common Implementation Mistakes
One frequent mistake is treating all loss terms as equally scaled by default. Their numerical sizes can differ drastically, causing the optimizer to ignore a physically essential requirement.
Another is using too few points near boundaries or discontinuities. A model may look accurate over most of the domain while failing exactly where stress, heat flux, or pressure gradient matters for design.
Engineers also sometimes infer more parameters than the data can identify. If two parameters have nearly identical effects on the observed signal, the PINN may return precise-looking values that are not uniquely supported.
🔐 Reliability, Safety, and Explainability
PINNs are often more interpretable than unconstrained black-box models because their governing equations and constraints are explicit. Still, their training process, architecture choices, data preprocessing, and weighting decisions can influence results.
For consequential applications, retain model versions, training settings, input datasets, unit conversions, and validation records. Reproducibility is an engineering requirement, not an administrative afterthought.
Outputs should also be presented at an appropriate level of confidence. An estimated internal temperature may support monitoring or maintenance planning, while a load-bearing safety decision may demand independent analysis and conservative margins.
🎓 Skills That Make PINNs Easier to Use Well
The foundation is still engineering mathematics. Useful topics include ordinary and partial differential equations, vector calculus, linear algebra, numerical methods, optimization, probability, and dimensional analysis.
On the computing side, practitioners benefit from programming, automatic differentiation frameworks, data handling, visualization, and version control. The goal is not to become an expert in every AI technique before starting.
Most importantly, learn to translate physical assumptions into mathematical statements. That skill determines whether a PINN receives meaningful physics to enforce.
🔭 Where the Field Is Heading
Current work continues to explore better training strategies, domain decomposition, adaptive sampling, uncertainty quantification, operator-learning approaches, and hybrids that connect neural models with established solvers.
Large multiphysics systems remain a central challenge. Real devices may couple mechanics, heat transfer, electromagnetics, chemistry, and controls, with uncertain interfaces between models.
The likely direction is not a single universal replacement for simulation software. It is a broader toolbox in which physics-based solvers, reduced-order models, sensor data, and learning methods are selected for the task at hand.
🧠 The Core Principle: Let Physics Constrain Learning
Physics-informed neural networks work by combining two sources of knowledge. Data tells the model what was observed; equations tell it what behavior should remain physically consistent between and beyond observations.
This can be powerful when measurements are limited, hidden states matter, and the governing physics is informative. It is less compelling when the physics model is unreliable, the problem is poorly posed, or a conventional solver already answers the question efficiently.
The most useful view of PINNs is not as a shortcut around engineering analysis, but as a way to embed engineering analysis inside data-driven learning. Their value depends on sound equations, credible conditions, thoughtful numerical treatment, and independent validation.
When mathematics, measurements, and engineering judgment are allowed to check one another, PINNs can turn limited data into more useful—though never assumption-free—insight. 📐🧠🔧